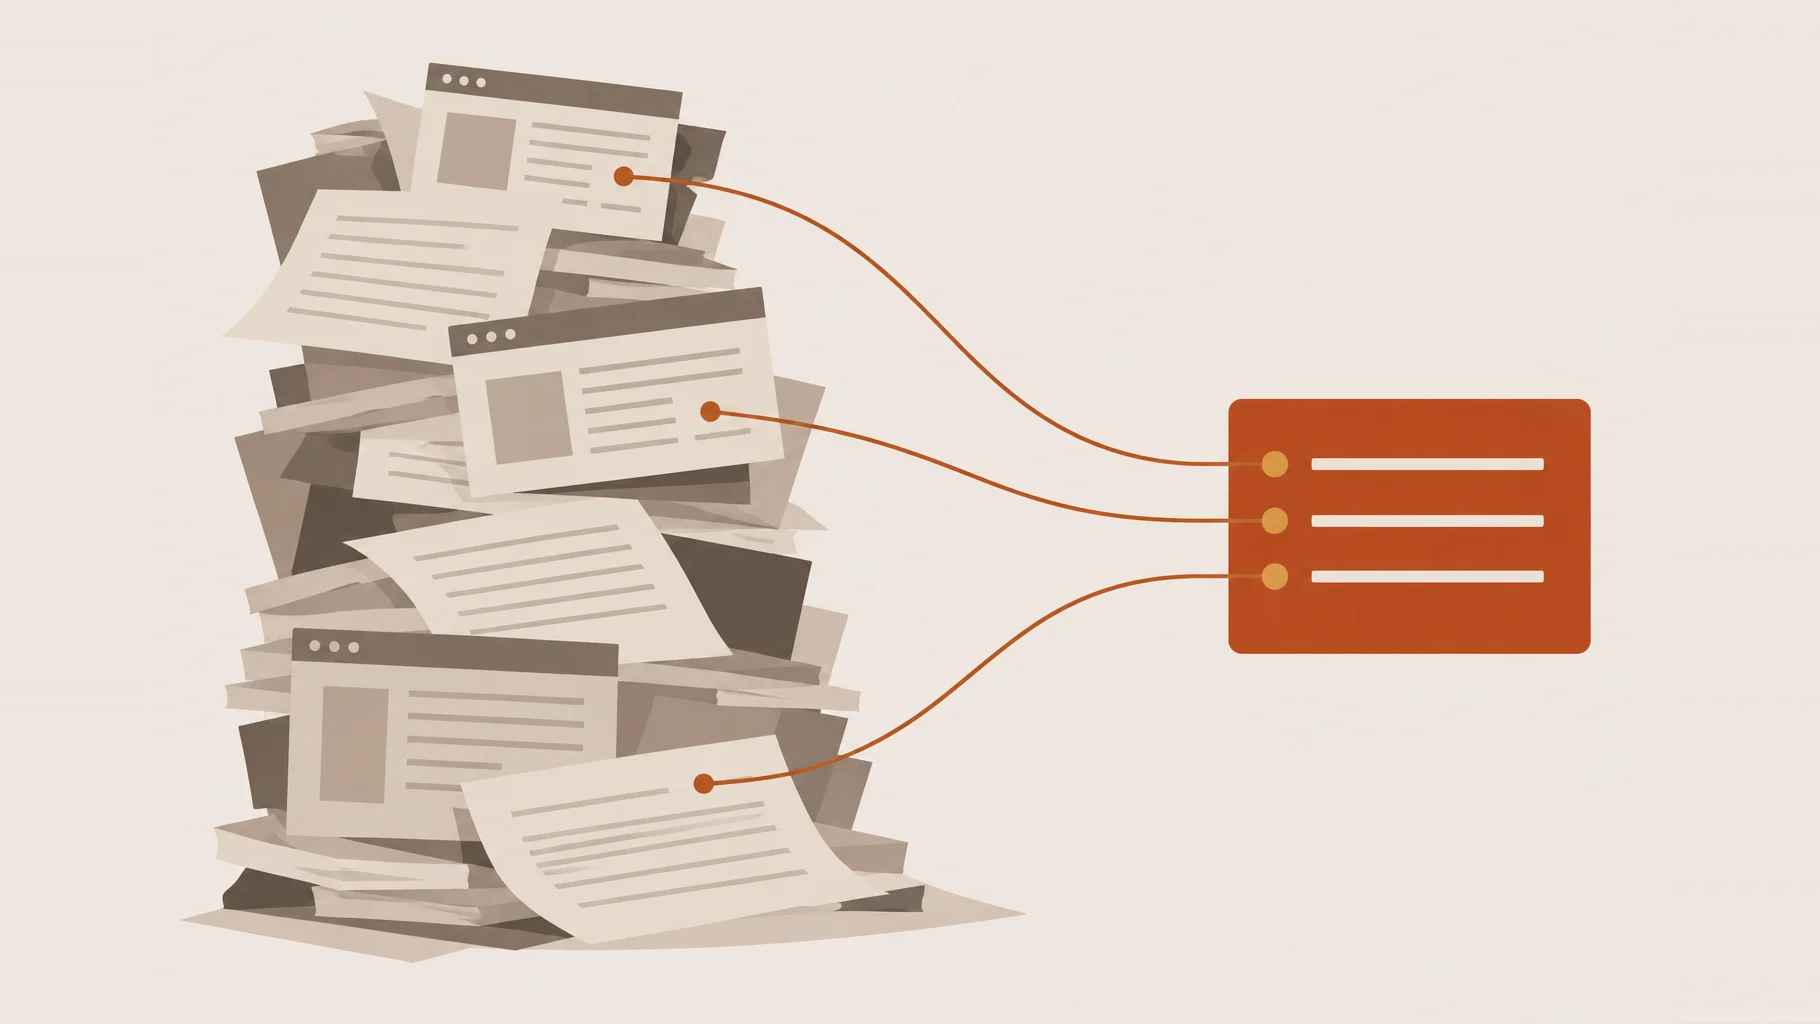
What is llms.txt? It’s a plain Markdown file that sits at the root of your website (yoursite.org/llms.txt) and gives AI tools a short, curated map of your most useful pages. Think of it as a reading list written for a language model: who you are, what matters, and links to the pages worth reading. That’s the whole job.
What it is not is a way to control AI bots. Plenty of advice online treats llms.txt as robots.txt for AI, with rules about which crawlers may read which folders. The format has no such rules, and no AI company has said its crawlers would follow them if it did. If you want to keep AI bots out of part of your site, that happens in robots.txt, and we’ll show you how below.
Where llms.txt came from
Jeremy Howard, cofounder of Answer.AI, proposed llms.txt in September 2024 at llmstxt.org. The problem he was solving is real. A web page is mostly navigation, scripts, cookie banners, and footer links, and a language model working with limited context wastes much of it wading through that. A clean Markdown summary that points to the good stuff is easier for a model to use.
The proposal got a second version in August 2026. It added standard ways for a page to point to a Markdown copy of itself and allowed llms.txt files in subfolders (a documentation site might keep one at /docs/llms.txt). It’s still a proposal, not a standard any browser, search engine, or AI company is bound by.
What goes in an llms.txt file
The only required part is a top-level heading with the name of your site or organization. After that, the spec suggests a one-paragraph summary in a blockquote, any notes you want to add, and then sections with H2 headings that list links. Each link can carry a short note after a colon. A section titled “Optional” is, by convention, where you put links an AI can skip when it’s short on room.
For a small nonprofit, a complete file might look like this:
# Northside Community Food Bank

> Nonprofit food bank serving the north side of the county since 1982. We run mobile pantries, a school backpack program, and volunteer shifts six days a week.

## Programs

- [Mobile pantry schedule](https://example.org/mobile-pantry/): Weekly stops, times, and what to bring
- [Backpack program](https://example.org/backpack-program/): How schools enroll students

## Get involved

- [Volunteer](https://example.org/volunteer/): Shift sign-up and age requirements
- [Donate](https://example.org/donate/): One-time and monthly giving

## Optional

- [2025 annual report](https://example.org/annual-report-2025/)
Notice what’s missing: no User-agent lines, no Allow, no Disallow. Those belong to robots.txt. Put them in llms.txt and nothing reads them.
You may also run into llms-full.txt, a single file holding the full text of every page. That’s a convention some documentation platforms invented, not part of the llms.txt proposal, and it mostly makes sense for software docs.
Does anyone actually read llms.txt?
Rarely, and this is the part most guides skip.
Google is the clearest. Its guide to optimizing for AI features in Search, last updated July 2026, says you don’t need machine-readable files, AI text files, or Markdown to appear in Google Search or its AI features, “as Google Search itself doesn’t use them.” It adds that creating an llms.txt file “will neither harm nor help your site’s visibility or rankings in Google Search.” That covers AI Overviews and AI Mode.
OpenAI, Anthropic, and Google all publish llms.txt files for their own developer documentation, which can make it look like they’ve endorsed the format. Publishing one is different from reading yours. None of their crawler documentation says their bots use llms.txt from other sites when they crawl or answer questions.
The traffic data agrees. In June 2026, Ahrefs studied 137,210 websites. About 28% had an llms.txt file, and 97% of those files got zero requests during May 2026. On the few that did get visits, named AI tools made fewer than one in five of the requests (OpenAI’s GPTBot 4.5%, Anthropic’s ClaudeBot under 1%). And no AI bot went looking for an llms.txt file that didn’t exist. Ahrefs’ verdict: if your goal is showing up in ChatGPT, Perplexity, or AI Overviews, “an llms.txt file is largely decoration.”
Where the format does earn its keep is developer documentation, where people point coding assistants at a site’s docs and a clean Markdown index saves real work. For a nonprofit or a professional services firm, the payoff is close to nothing today.
How to actually control AI crawlers
If what you wanted from llms.txt was control (keeping AI out of a members area, or out of model training), robots.txt is the file that does it. The major AI companies publish the names their crawlers answer to, and most of them now split those crawlers by purpose, which turns this into a real decision rather than an on/off switch.
Training crawlers collect content to train AI models: OpenAI’s GPTBot, Anthropic’s ClaudeBot, and Common Crawl’s CCBot, whose public dataset many models train on. Google-Extended and Applebot-Extended aren’t crawlers at all. They’re tokens you can name in robots.txt to tell Google and Apple not to use content their regular crawlers already collected for AI training (Google-Extended also covers grounding answers in Gemini). Blocking either one does not affect Google Search or Apple’s search results.
Search crawlers decide whether you show up in AI answers: OpenAI’s OAI-SearchBot, Anthropic’s Claude-SearchBot, and PerplexityBot. OpenAI says plainly that sites blocking OAI-SearchBot won’t be shown in ChatGPT search answers.
Most nonprofits want the second group in. If someone asks ChatGPT where to volunteer in your city, you want to be the answer. Whether to opt out of training is a values call, and a reasonable one either way. A robots.txt that opts out of training while staying visible in AI search looks like this:
# Opt out of AI model training
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: Applebot-Extended
Disallow: /

# Keep every bot out of the members area
User-agent: *
Disallow: /members/
Two limits to know. Robots.txt is an honor system, so it stops well-behaved crawlers and nothing else, and anything truly private belongs behind a login. And fetches a person triggers directly (ChatGPT-User or Perplexity-User opening a link someone asked about) may not follow robots.txt at all, according to OpenAI’s and Perplexity’s own documentation.
How to set up llms.txt in WordPress
If your site runs Yoast SEO, you already have it. Yoast added llms.txt in version 25.3 (June 2025), free for everyone. Switch it on and Yoast builds the file for you: the five most recently updated items of each type from the past year (posts, pages, and other content types such as case studies, with cornerstone content first), plus the categories and tags with the most content, refreshed weekly. You can pick the pages yourself if the automatic list isn’t what you want.
All in One SEO includes llms.txt in its free version (llms-full.txt needs Pro), and Rank Math has a free llms.txt module that lists each page’s title, URL, and a short description. Writing one by hand works too: save a Markdown file named llms.txt and upload it to your site’s root folder.
So, does your website need an llms.txt file?
Not really, but if your SEO plugin makes one with a single switch, flip it. It costs nothing, Google says it won’t hurt, and if AI tools start reading these files later you’ll already have one. Just don’t pay anyone to build one, and don’t expect it to move your traffic.
The work that gets a site cited in AI answers is the same work that gets it found in search: pages Google and AI crawlers can actually reach, plain answers to the questions people ask, accurate structured data, and other sites mentioning you. We’ve written more about optimizing content for AI search, and it’s a core part of our SEO work and AI website optimization.
llms.txt FAQs
Is llms.txt the same as robots.txt?
No. Robots.txt tells crawlers what they may and may not fetch, and the major search and AI crawlers honor it. Llms.txt is a reading list that points AI tools toward your best pages. It has no access rules, and putting robots.txt directives in it does nothing.
Does llms.txt help with Google rankings or AI Overviews?
No. Google’s own documentation says Google Search ignores llms.txt files, including for its AI features, and that having one neither helps nor hurts your visibility.
Can llms.txt stop ChatGPT from using my content?
No. To opt out of OpenAI’s model training, block GPTBot in robots.txt. To stay out of ChatGPT search answers as well, block OAI-SearchBot, though most organizations want to appear there.
What is llms-full.txt?
A single file containing the full text of a site’s content, popularized by documentation platforms. It isn’t part of the llms.txt proposal. All in One SEO generates one in its Pro version.
Where does the llms.txt file go?
At the root of your domain, so it loads at yoursite.org/llms.txt. The 2026 version of the proposal also allows files in subfolders, such as /docs/llms.txt for a documentation section.